Structured screening
Build the question set once. Every applicant answers the same thing.
Role templates for 40+ engineering tracks
We run the structured first round. Same questions, same rubric, ranked shortlist.
Capabilities
Build the question set once. Every applicant answers the same thing.
Role templates for 40+ engineering tracks
Your trainers and admins score every recording against your rubric, right inside the platform.
Structured rubric review, no external vendors
Assign structured courses, track completion, and issue certificates the moment candidates finish.
Curriculum, quizzes and certificates built in
Rankings, distributions and integrity flags in one panel-ready view.
Exports to CSV or PDF
The platform
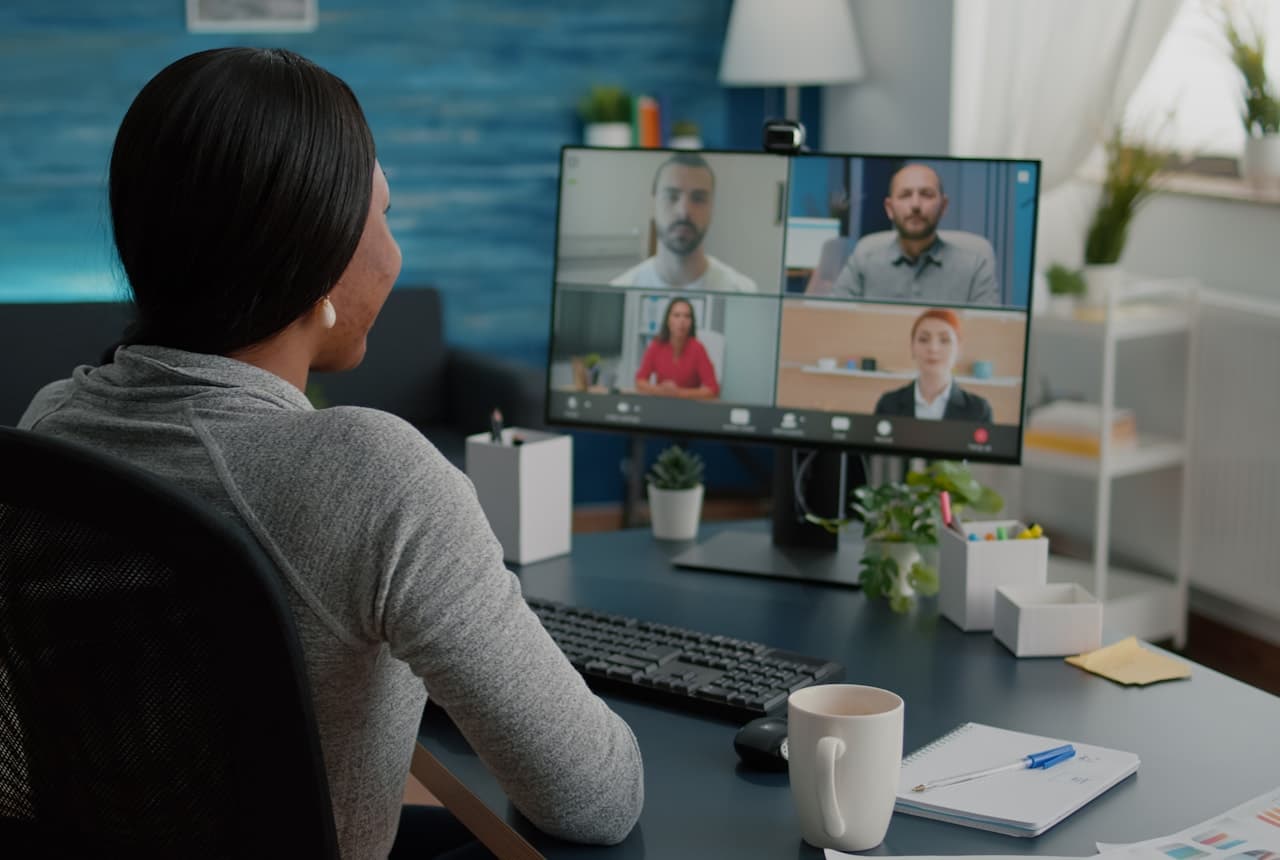
Reviewers score while they watch. Every rubric line is timestamped.
 Reviewed by domain specialistsBook a walkthrough
Outcomes
Medians across teams three months in.
Read the write-upsHow it works
Set it up once per role. The loop runs itself.
Pick the competencies, set the weights.
One link. Any device, any timezone.
Your team scores against the rubric, right in the platform.
A ranked shortlist with the evidence attached.
Industries
One rubric per level keeps standards steady when six squads hire at once.
Trust and governance
FAQ
How a round runs, who scores it, what happens to the recordings, and what we will not claim.
Still deciding?
Thirty minutes on your own roles, with someone who has set up a few hundred of them.
Book a walkthroughHow a round runs
They open one link, check their camera and microphone, then answer your questions one at a time on camera. Each question shows the time allowed and how it will be scored before recording starts.
There is nothing to install and no scheduling. A session runs in the browser on a laptop or a phone, in whatever timezone the candidate is in, and most role sets take 25 to 40 minutes end to end.
You do, once per role. Start from a template (there are role templates for 40+ engineering tracks), then cut what does not apply, add your own questions and set the weight of each competency.
After that the set is fixed for every applicant to that role. That is the whole point of a structured round: the comparison is only fair if everyone answered the same thing against the same weights.
About an afternoon for the first one, less for every role after it, because you clone an existing set and adjust. Teams typically invite their first candidates the same week they start.
You decide per question. Retakes can be off, limited to a fixed number, or open. Whatever you choose is shown to the candidate before they record, along with how many attempts they have used.
Whatever you allow, the reviewer sees the attempt count alongside the answer, so a heavily retaken response is never silently presented as a first take.
Scoring and reviewers
Your own trainers and admins, using the rubric you set for the role. Whoever grades a submission scores against the same weighted rubric line by line.
You can spread scoring across as many reviewers as you like, or keep it to a single trainer for smaller cohorts.
As fast as your team clears the queue. Every submission lands ready to score inside the platform, so most cohorts see results the same day they're graded rather than waiting on a separate tool.
Every reviewer scores against the same written rubric attached to the role, so criteria don't vary person to person.
Admins can open any scored submission and see the reviewer's notes next to the recording, so drift is easy to catch and correct early.
Disagreement is surfaced, not averaged away. When two scores on the same rubric line differ, both scores and each reviewer's notes stay attached to the submission for an admin to weigh.
You are deciding from evidence, so a genuinely split answer should look split rather than resolving into a confident-looking single number.
Every rubric line gets a band and a timestamped note pointing at the moment in the recording that justifies it, plus a weighted total from the weights you set.
Nothing is a black box: you can open any score, read the reviewer's reasoning and jump straight to the part of the answer it refers to.
Integrity and fairness
No. Integrity signals are advisory and a human decides every time. Nothing in the platform rejects, filters or ranks a candidate out on its own.
A signal appears as a confidence note next to the answer for a reviewer to weigh, not as a verdict.
Quiet, checkable things: whether the session ran in one continuous take, whether the person on camera stayed consistent, and whether an answer's pacing suggests it was being read rather than spoken.
Each flag says what it observed in plain language. There is no overall trust score, because a single number invites exactly the kind of automated decision we will not make.
Per-candidate accommodations are set before the invitation goes out: extra time, extra attempts, or a written response instead of a recorded one. The reviewer scores the same rubric either way and sees that an accommodation applied, not what it was.
Sessions are keyboard navigable and captioned, and a candidate can raise a technical problem mid-session without losing the work already recorded.
It narrows where bias can enter, which is the honest claim. Everyone answers the same questions against the same weights, and reviewers score one rubric line at a time rather than forming an overall impression.
It does not remove bias, and we will not claim it does. What it gives you is a record: because every score keeps its rubric line, reviewer and timestamp, you can audit your own decisions across a cohort and see patterns you would otherwise argue about from memory.
Data, tooling and commitment
You pick the region, or run in a dedicated environment. Everything is encrypted in transit and at rest, and access is scoped per role, so a reviewer on one role cannot see another.
Retention is on your schedule, not ours. Set the window and recordings expire on it. Candidates agree to recording before a session starts and that consent is kept with the session.
Scores, rankings and distributions export to CSV or push into your ATS, so the shortlist lands where your team already works and you are not asking a panel to log into another tool to read a result.
Medians from teams running at least 200 sessions, measured against each team's own baseline rather than an industry average: 2.5x faster to a shortlist, 83% of reviewer hours returned compared with panel-led first rounds, a 4.3 out of 5 candidate rating, and 31% more offers accepted on the back of a shorter time to decision.
Those are medians, not guarantees. Teams with an already-tight process see smaller gaps on speed and a bigger one on consistency.
No. Start on your own roles with nothing to install, and keep going only if the first cohort is worth it. Most teams are live in under a week.
Thirty minutes, your own roles, nothing to install.